Bright Data Twitter Scraper vs Weir (2026): Pricing
The Bright Data Twitter scraper bills $1.50 per 1,000 records. See its datasets, async jobs and worked costs for 10,000 profiles and 1M posts next to Weir.
Tarun Khatri
Published · Updated · 7 min read
The Bright Data Twitter scraper fits batch jobs and ready-made datasets at scale; Weir fits apps that want X (Twitter) data back in one call.
Bright Data sells proxies, scrapers and datasets, and its Twitter (X) Scraper API bills per record. We run Weir, so every Bright Data fact here comes from its own pages and docs, checked on 22 October 2026.
Weir returns one post in one call:
curl https://api.weirapp.io/v1/x/posts/2111172163776708859 \
-H "Authorization: Bearer $WEIR_API_KEY"Bright Data Twitter scraper or Weir: which fits you?
It depends on the size of the job and where the data has to land.
Bright Data is built for volume: big async jobs, files delivered to cloud storage, and datasets you can buy outright. Weir is a REST API and MCP server for public X and Reddit data, billed per result from prepaid credits.
| Bright Data | Weir | |
|---|---|---|
| Billing | Per record | Prepaid credits, per result |
| 1,000 X posts | $1.30 to $1.50 | $0.105 to $0.21 |
| Free tier | 5,000 records a month | 5,000 credits a month |
| Input | X URLs or usernames | Keywords, handles or ids |
| Keyword search | Not in its X docs | Yes, with X's operators |
| Delivery | Async jobs, webhook, S3 | JSON in the same response |
| Ready-made datasets | 145.7M+ X records, from $250 | None |
| Other sites | 1,400+ pre-built scrapers |
Weir's post price counts 1 credit per call, at 20 posts a call.
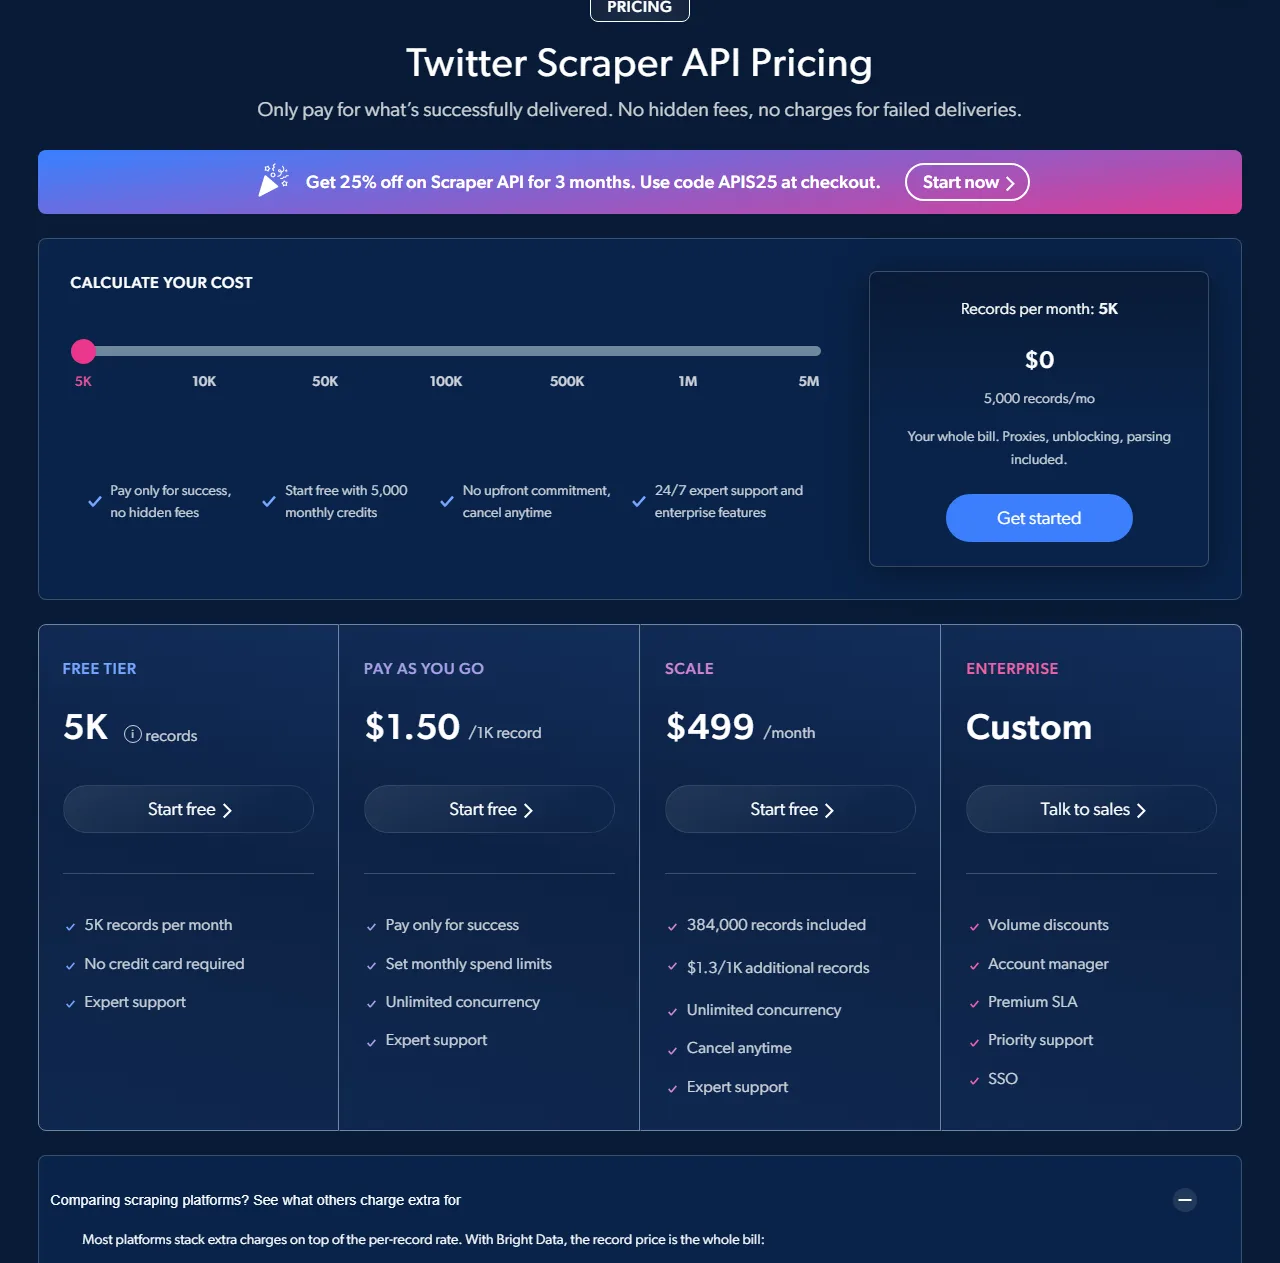
Bright Data Twitter scraper pricing: $1.50 per 1,000 records
Bright Data charges per record, which its pricing page defines as "one extracted item, shown as a row in the table." By that rule, one post or one profile is one record.
Read the fine print too:
- Scale adds records past 384,000 at $1.30 per 1,000.
- Failed deliveries are free. You "only pay for what's successfully delivered."
- Free records renew on the 1st of each month and don't roll over.
- Code APIS25 takes 25% off the Scraper API for three months.
Weir's packs run from $5 to $1,000 and never expire. Failed calls cost nothing there either.
What 10,000 profiles and 1 million posts cost
Weir costs less at both volumes, by a little on profiles and by a lot on posts.
10,000 X profiles a month:
- Bright Data: 10,000 records, less 5,000 free, leaves 5,000. At $1.50 per 1,000, that is $7.50.
- Weir: a profile costs 2 credits plus 1 for the call. 10,000 × 3 = 30,000 credits, less 5,000 free, leaves 25,000: one $5 pack.
If you already hold account ids, Weir's batch lookup takes 100 per call. That cuts the bill to 20,100 credits. After the free grant, that is $3.02 at the $5 pack's rate.
1 million X posts a month, counting one post as one Bright Data record:
- Bright Data, pay as you go: 995,000 paid records at $1.50 per 1,000 is $1,492.50.
- Bright Data, Scale: $499, plus 616,000 extra records at $1.30 per 1,000, is $1,299.80.
- Weir: 50,000 calls + 1,000,000 posts = 1,050,000 credits. Less 5,000 free, you pay $104.50 at the $1,000 pack's rate.
How does the Bright Data X scraper return data?
Bright Data's X docs cover two scrapers: profiles and posts. You send X URLs, or a username to discover a profile, and get JSON, NDJSON, CSV or Parquet back.
Its docs say the sync endpoint, /scrape, works best with one input. It waits up to 1 minute, then answers HTTP 202 with a snapshot_id, and the job carries on.
For anything bigger, you run a job:
- Trigger a jobPOST /datasets/v3/trigger with up to 1 GB of URLs.
- Wait for the snapshotPoll its progress with the snapshot_id.
- Collect the recordsDownload them, or have them sent to a webhook, S3 or Snowflake.
A post job can also discover an account's posts from its profile URL, with start and end dates.
Weir answers every call, from one profile to a search page of about 20 posts, in the same response.
Bright Data Twitter dataset: when buying beats scraping
Bright Data also sells X data that is already collected. Its dataset page lists two X datasets, posts and profiles:
You can buy once or refresh twice a year, quarterly or monthly. Files come as JSON, CSV or Parquet, delivered to Snowflake, S3, Google Cloud, Azure or SFTP.
Weir has no datasets. It reads X live, so a backfill means paging through calls; our guide to historical Twitter data shows how far back that goes.
When to choose Bright Data
Choose Bright Data for very large jobs, data warehouses, or many sites at once.
Good
- Ready-made X datasets, refreshed on a schedule
- Async jobs of up to 1 GB of input each
- Delivery to S3, Snowflake, Azure, Google Cloud, SFTP or a webhook
- ISO 27001, SOC 2 controls, GDPR and CCPA, by its own page
- 1,400+ pre-built scrapers, from LinkedIn to Amazon
- 5,000 free records a month, and 24/7 support on every plan
Watch out
- $1.30 to $1.50 per 1,000 X records
- No keyword search in its X docs
Its page also says every use case is reviewed by a Compliance and Ethics team, with a Know Your Customer process. Weir lists no certifications like these.
When to choose Weir
Weir is the better fit for X search, live answers and lower prices per post.
Good
- $0.105 to $0.21 per 1,000 X posts, by pack
- X search by keyword, with operators, dates and like floors
- Replies, quotes, followers, Lists and Spaces endpoints
- One request, one JSON response
- Reddit on the same key, and monitors with signed webhooks
- Packs from $5 that never expire
Watch out
- 30 to 600 requests a minute, by tier
- No datasets and no cloud-storage delivery
Migrating from Bright Data to Weir
On Bright Data, a post is a POST to its sync endpoint with the posts dataset id:
curl -X POST "https://api.brightdata.com/datasets/v3/scrape?dataset_id=gd_lwxkxvnf1cynvib9co&format=json" \
  -H "Authorization: Bearer $BRIGHT_DATA_API_KEY" \
  -H "Content-Type: application/json" \
  -d '[{"url": "https://x.com/XDevelopers/status/2111172163776708859"}]'
Weir's call is at the top. We ran it through Weir's MCP server on 22 October 2026, and it cost 2 credits. Trimmed:
{
  "id": "2111172163776708859",
  "text": "New guide to the 𝕏 Chat API from @santiagomed: ...",
  "createdAt": "2026-10-16T19:07:22.000Z",
  "author": { "username": "XDevelopers", "name": "Developers" },
  "likeCount": 120,
  "retweetCount": 18,
  "replyCount": 9,
  "viewCount": 14787,
  "bookmarkCount": 37
}
The post it quotes came back too, inside quotedPost, at no extra charge. These fields change name:
| Bright Data post field | Weir |
|---|---|
description |
text |
date_posted |
createdAt |
user_posted |
author.username |
likes |
likeCount |
reposts |
retweetCount |
replies |
replyCount |
views |
viewCount |
quoted_post |
quotedPost |
id and url keep their names. Weir sends what each call cost in the x-credits-charged header.
When not to use Weir
- You want a dataset, not an API. Bright Data sells X records already collected.
- Your data must land in S3 or Snowflake. Bright Data delivers there; Weir returns JSON to your code.
- Your review needs ISO 27001 or SOC 2. Bright Data lists them, and Weir doesn't.
- You need to post. Neither can, so use the official X API.
FAQ
How much does the Bright Data Twitter scraper cost?
As of October 2026, it costs $1.50 per 1,000 records on pay as you go. The Scale plan is $499 a month for 384,000 records, then $1.30 per 1,000. The first 5,000 records each month are free.
Is the Bright Data Twitter API the official X API?
No. Bright Data's Twitter (X) Scraper API is its own product. It collects public profiles and posts from X URLs or usernames, and returns them as JSON, CSV or other formats.
How much is the Bright Data Twitter dataset?
Its dataset page lists a $250 minimum order, at up to $0.0025 per record. A monthly refresh saves 80%, and you can ask for a sample before you buy.
Is Weir a cheaper Bright Data alternative for X?
Per post, yes: we run Weir, and it costs $0.105 to $0.21 per 1,000 posts, against $1.30 to $1.50. For datasets, cloud delivery or other sites, Bright Data does more.
Sources
All checked 22 October 2026:
- Bright Data Twitter (X) Scraper API and pricing: https://brightdata.com/products/web-scraper/twitter and https://brightdata.com/pricing/web-scraper
- Bright Data Twitter datasets: https://brightdata.com/products/datasets/twitter
- Bright Data X Scraper API docs and input schemas: https://docs.brightdata.com/products/scrapers/twitter/introduction, https://docs.brightdata.com/products/scrapers/twitter/send-first-request, https://docs.brightdata.com/scrapers/gd_lwxkxvnf1cynvib9co.json and https://docs.brightdata.com/scrapers/gd_lwxmeb2u1cniijd7t4.json
- Bright Data Scraper API limits: https://docs.brightdata.com/products/scrapers/limits
- Weir pricing and docs: https://weirapp.io/pricing, https://docs.weirapp.io/billing and https://docs.weirapp.io/pagination
- Our Weir lookup of an @XDevelopers post, 22 October 2026