Twitter Sentiment Analysis Datasets: 8 Compared (2026)
Sentiment140, TweetEval and 6 more Twitter sentiment analysis datasets: size, labels, years, license and the catch, plus 40 fresh airline posts we labeled.
Weir Team
Published · Updated · 7 min read
Twitter sentiment analysis datasets in 2026 are old, frozen sets such as Sentiment140, TweetEval, the US airline set and Tweet Sentiment Extraction.
It's for you if you need labeled X (Twitter) posts to train or test a model. You get each set's facts and catch, then a tested way to label 2026 posts with Weir, which we run.
Paste this into Claude or ChatGPT with Weir connected to label a fresh sample now:
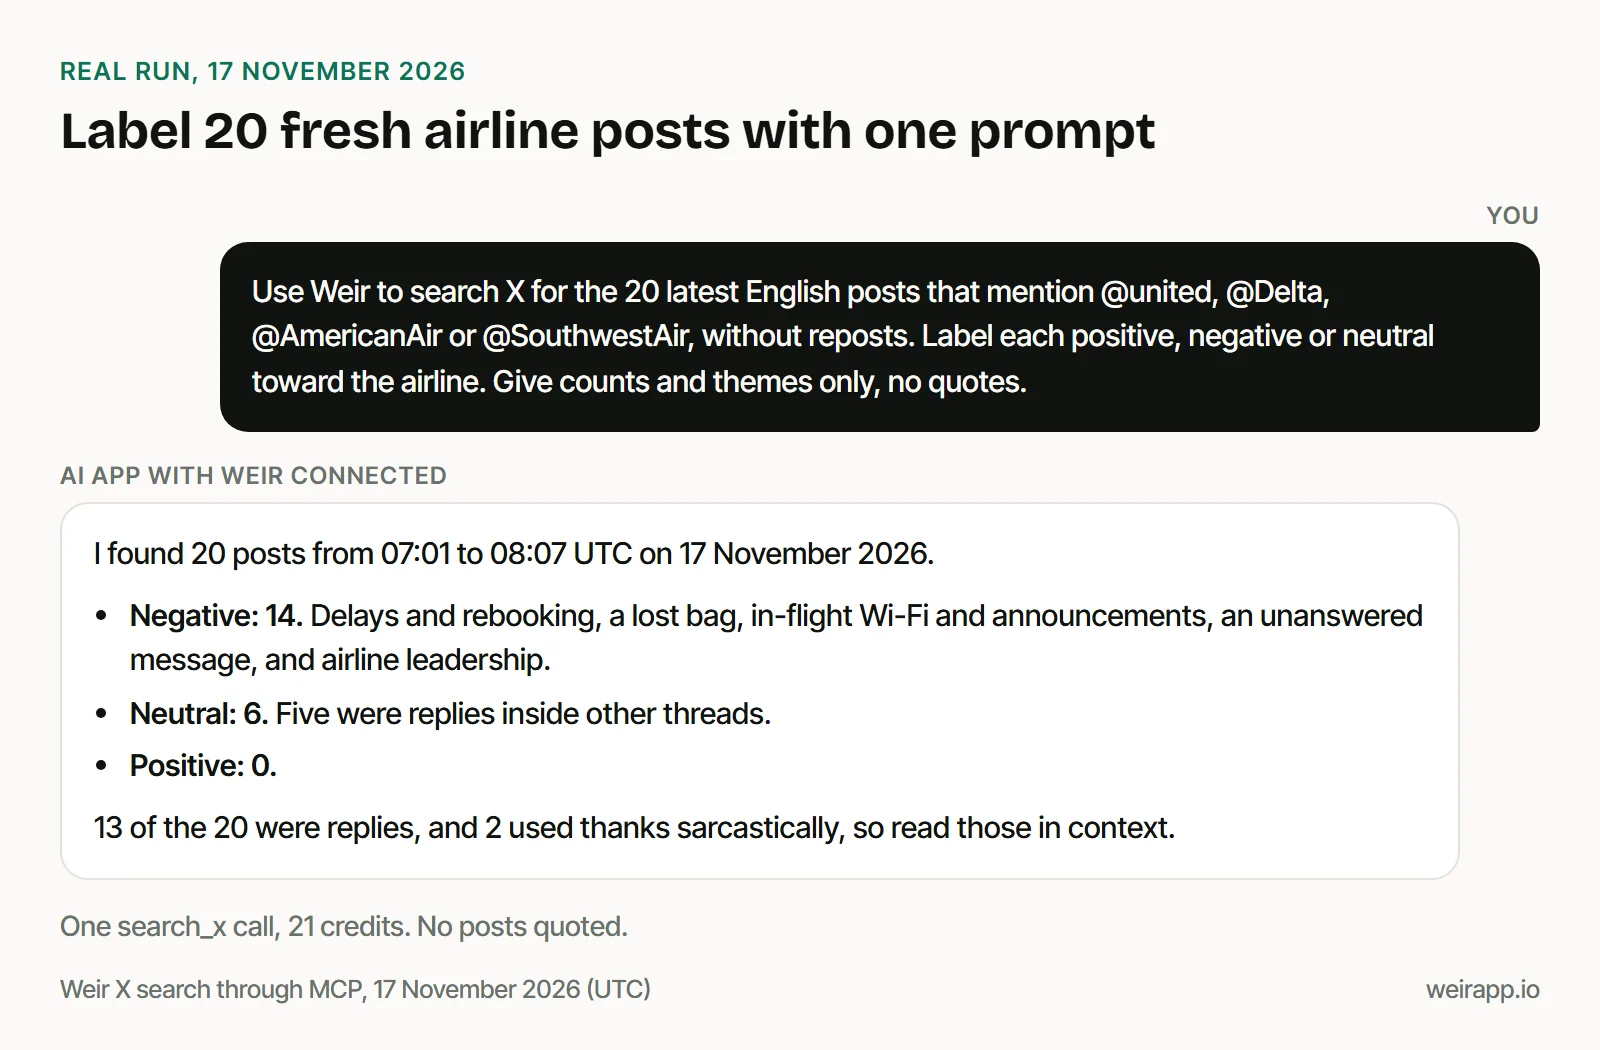
Use Weir to search X for the 20 latest English posts that mention @united, @Delta, @AmericanAir or @SouthwestAir, without reposts. Label each positive, negative or neutral toward the airline. Give counts and themes only, no quotes.- Pick a datasetMatch its labels and years to your task.
- Read its catchLicense, label source, IDs only.
- Collect fresh posts20 posts cost 21 credits.
- Label 20 yourselfOne rule, three labels.
- Test a modelCount where it agrees with you.
Twitter sentiment analysis datasets, compared
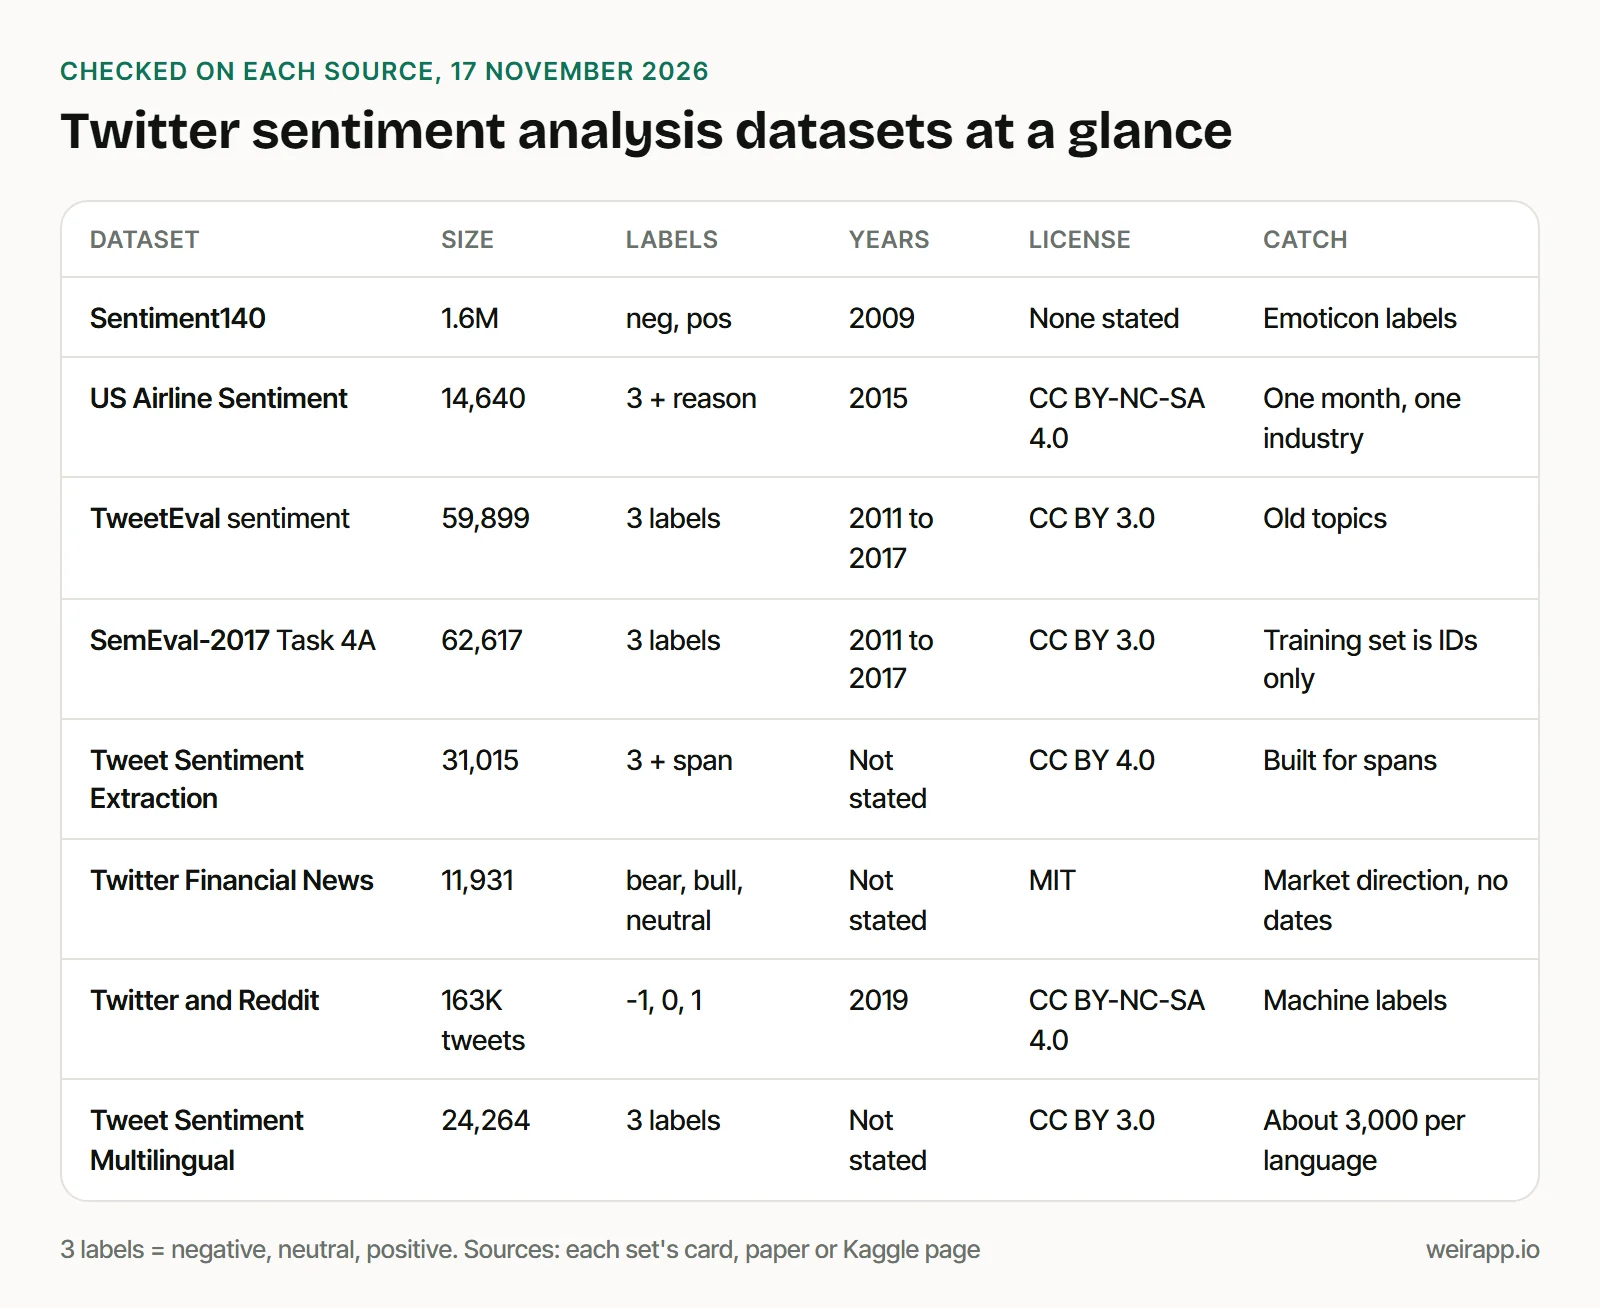
We checked each set's own card, paper or Kaggle page on 17 November 2026. "3 labels" means negative, neutral and positive:
| Dataset | Size | Labels | Years | License |
|---|---|---|---|---|
| Sentiment140 | 1.6M | negative, positive | 2009 | None stated |
| Twitter US Airline Sentiment | 14,640 | 3 labels + reason | 2015 | CC BY-NC-SA 4.0 |
| TweetEval, sentiment task | 59,899 | 3 labels | 2011 to 2017 | CC BY 3.0 |
| SemEval-2017 Task 4A | 62,617 | 3 labels | 2011 to 2017 | CC BY 3.0 |
| Tweet Sentiment Extraction | 31,015 | 3 labels + span | Not stated | CC BY 4.0 |
| Twitter Financial News | 11,931 | bearish, bullish, neutral | Not stated | MIT |
| Twitter and Reddit (Kaggle) | 163K tweets | -1, 0, 1 | 2019 | CC BY-NC-SA 4.0 |
| Tweet Sentiment Multilingual | 24,264 | 3 labels | Not stated | CC BY 3.0 |
Size counts every row you download, train and test together. The catch in each:
- Sentiment140's labels came from emoticons, which its authors then removed from the text.
- The airline set covers one industry in one month, and its license bars you from commercial use.
- TweetEval is a fixed benchmark, good for comparing with papers, but its newest tweets are from early 2017.
- SemEval ships its training tweets as IDs only, and many no longer come back.
- Tweet Sentiment Extraction was built for another job: finding the words that carry the mood.
- Twitter Financial News labels market direction, bearish or bullish, and its card gives you no dates.
- The Twitter and Reddit set has machine labels. Its card credits "NLP" during cleaning, and it covers one 2019 election.
- Tweet Sentiment Multilingual is small: about 3,000 tweets in each of eight languages, with no Japanese or Chinese.
For other X data, like stream archives, see our guide to Twitter datasets.
Why so many tweet datasets ship only post IDs
X itself gives you no sentiment labels. Its API data dictionary lists no sentiment field on a post, and it points you to the text field for sentiment analysis.
As of 17 November 2026, X's Developer Policy says you "may only distribute Post IDs, Direct Message IDs, and/or User IDs." The cap is 1,500,000 post IDs to any one recipient every 30 days.
So SemEval hands you numbers to look up again, which is called hydrating. We tried 100 random IDs from its 2013 training file:
The 62 that came back were posted between August 2011 and November 2012. The policy also has you delete stored posts once they're deleted on X, so old sets shrink. For the whole job, see how to hydrate tweet IDs.
How to build a fresh Twitter sentiment dataset in 2026
None of the eight holds a 2026 post, so collect your own with a tested search, then label a sample.
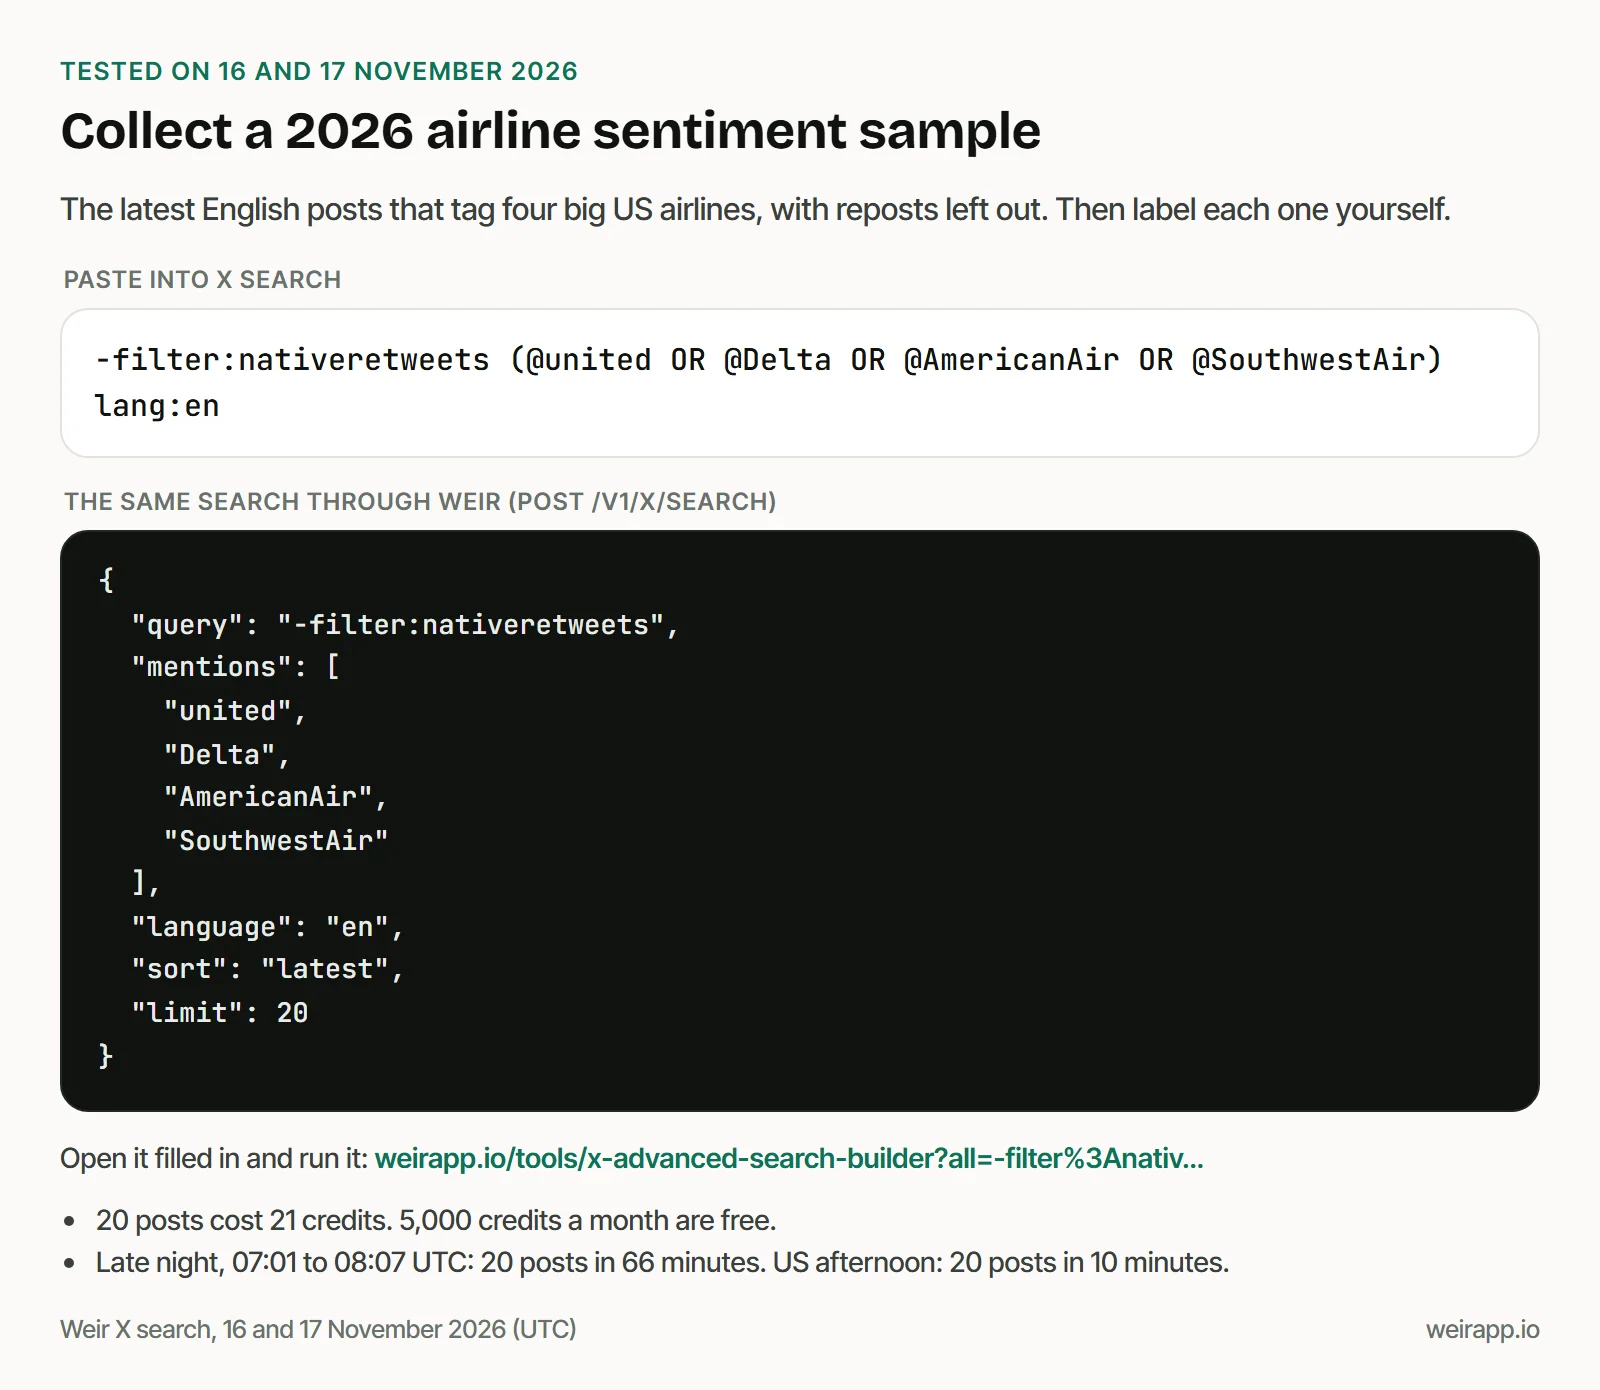
Recipe 1: posts that tag big US airlines. It repeats the 2015 airline set's idea with today's posts:
-filter:nativeretweets (@united OR @Delta OR @AmericanAir OR @SouthwestAir) lang:enOpen it filled in. On 17 November it returned 20 posts from 66 minutes of late-night US traffic. An afternoon hour on 16 November filled 20 posts in 10 minutes.
Recipe 2: posts for a stock sentiment dataset. Swap in your own ticker:
$NVDA -filter:nativeretweets lang:en min_faves:10 -filter:repliesOpen it filled in. Of the 20 posts it returned on 17 November, 15 were about Nvidia or its stock. Four were promos from crypto exchanges and wallets, so drop those before you label.
What it costs: 20 posts cost 21 credits; 5,000 credits a month are free; $5 buys 25,000.
We labeled 40 airline posts: the 2026 split
Our rule was one question: how does the post feel about the airline it tags? A post that isn't about the airline counts as neutral.
| Sample | Negative | Neutral | Positive |
|---|---|---|---|
| 2015 airline set, 14,640 tweets | 63% | 21% | 16% |
| Our 40 posts, November 2026 | 25 (63%) | 14 (35%) | 1 (2.5%) |
The negative share matched 2015 almost exactly. Positive posts nearly vanished, and our one was a travel-news roundup.
Forty posts is a small sample: treat it as a worked example.
Three things will make your labeling hard too:
- Most posts were replies. 29 of 40 sat inside other threads, and some made no sense without the post above.
- Sarcasm hides. Three complaints were sarcastic, and two used "thanks" or "thank you", which VADER's word list scores as positive.
- Some accounts posted twice. Our 40 posts came from 35 accounts, so cap posts per account.
How to use Twitter RoBERTa sentiment on your sample
CardiffNLP's twitter-roberta-base-sentiment-latest is a common pick, with 2,375,099 downloads in the month to 17 November 2026. Its model card says it learned from about 124 million tweets from 2018 to 2021, then was tuned on TweetEval.
It gives you three labels: 0 for negative, 1 for neutral and 2 for positive. The card says it suits English, and its license is CC BY 4.0.
To use it on your sample:
- Install
transformersand PyTorch. - Load
cardiffnlp/twitter-roberta-base-sentiment-latestin a sentiment pipeline, as the card shows. - Score your 20 labeled posts and count where the model agrees with you.
- Decide. If it agrees on most, score the rest. If not, label more posts and fine-tune it.
We didn't run the model for this guide; these steps follow its card. It never saw a post after 2021, so check new slang yourself. For a scorer with no model download, our Twitter sentiment analysis in Python guide uses VADER.
When not to use Weir
- You need a score that compares with papers. Use TweetEval's fixed splits instead.
- You need a million labels today. Sentiment140 is free, and labeling fresh posts takes your time.
- You need data licensed by X. Only X's own API or a deal with X gives you that; X lists $0.005 per post read.
Weir reads public posts only and isn't licensed by X, so access can change.
FAQ
Which tweets dataset is best for sentiment analysis?
It depends on your job. Use TweetEval to compare with published results, Sentiment140 for volume, and the airline set for customer service. None covers 2026, so add a fresh sample you label yourself.
Is Sentiment140 labeled by humans?
Only its 498 test tweets. Its 1.6 million training tweets got their labels from emoticons, which the authors then removed from the text. So you get noisy labels, and no neutral class in training.
Where can I download the Twitter US Airline Sentiment dataset?
On Kaggle, from Figure Eight's page, as a CSV and a SQLite file. It holds 14,640 tweets about six US airlines from February 2015. Its CC BY-NC-SA 4.0 license rules out commercial use. Copies also sit on Hugging Face.
Can I use Twitter sentiment datasets commercially?
Check each license first. The airline set and the Twitter and Reddit set are non-commercial, Sentiment140 states no open license, and the financial set is MIT. X's terms cover the posts too. This isn't legal advice.
Sources
Checked on 17 November 2026; Kaggle pages as Wayback copies, dated in brackets:
- Sentiment140 paper (2009) and card: https://www-cs.stanford.edu/people/alecmgo/papers/TwitterDistantSupervision09.pdf and https://huggingface.co/datasets/stanfordnlp/sentiment140
- Twitter US Airline Sentiment on Kaggle (13 October 2026), and the Hugging Face copy we counted: https://www.kaggle.com/datasets/crowdflower/twitter-airline-sentiment and https://huggingface.co/datasets/osanseviero/twitter-airline-sentiment
- TweetEval card: https://huggingface.co/datasets/cardiffnlp/tweet_eval
- SemEval-2017 Task 4 paper, and the data page with its README: https://aclanthology.org/S17-2088.pdf and https://alt.qcri.org/semeval2017/task4/index.php?id=data-and-tools
- Tweet Sentiment Extraction on Kaggle (20 September 2020), and its sizes: https://www.kaggle.com/c/tweet-sentiment-extraction/overview and https://huggingface.co/datasets/mteb/tweet_sentiment_extraction
- Twitter Financial News Sentiment card: https://huggingface.co/datasets/zeroshot/twitter-financial-news-sentiment
- Twitter and Reddit set on Kaggle (20 April 2026): https://www.kaggle.com/datasets/cosmos98/twitter-and-reddit-sentimental-analysis-dataset
- Tweet Sentiment Multilingual card: https://huggingface.co/datasets/cardiffnlp/tweet_sentiment_multilingual
- CardiffNLP Twitter RoBERTa model card: https://huggingface.co/cardiffnlp/twitter-roberta-base-sentiment-latest
- VADER lexicon: https://github.com/cjhutto/vaderSentiment
- X Developer Policy: https://docs.x.com/developer-terms/policy
- X API data dictionary: https://docs.x.com/x-api/fundamentals/data-dictionary
- X API pricing: https://docs.x.com/x-api/getting-started/pricing
- Weir search, post lookup and billing: https://docs.weirapp.io/reference/x/searchX, https://docs.weirapp.io/reference/x/getXPosts and https://docs.weirapp.io/billing
- Our Weir calls, 16 and 17 November 2026: 3 searches and a 100-ID lookup, 126 credits